Explore Seqera Cloud
When you sign up for Seqera Cloud with a verified work email, Platform sets up a workspace with starter resources and $100 in free credits. Launch the nf-core/rnaseq pipeline, follow the run, and find its input, output, and compute in your workspace.
You need the following:
- A Seqera Cloud account created with a verified work email
Accounts created with a generic email domain, such as Gmail, aren't eligible for free resources. You can still sign in, but Platform doesn't create an organization or workspace for you.
Your free resources
When you first sign in, Platform creates an organization and workspace for you and sets up starter resources. Setup typically takes under a minute. A welcome dialog confirms when your resources are ready.
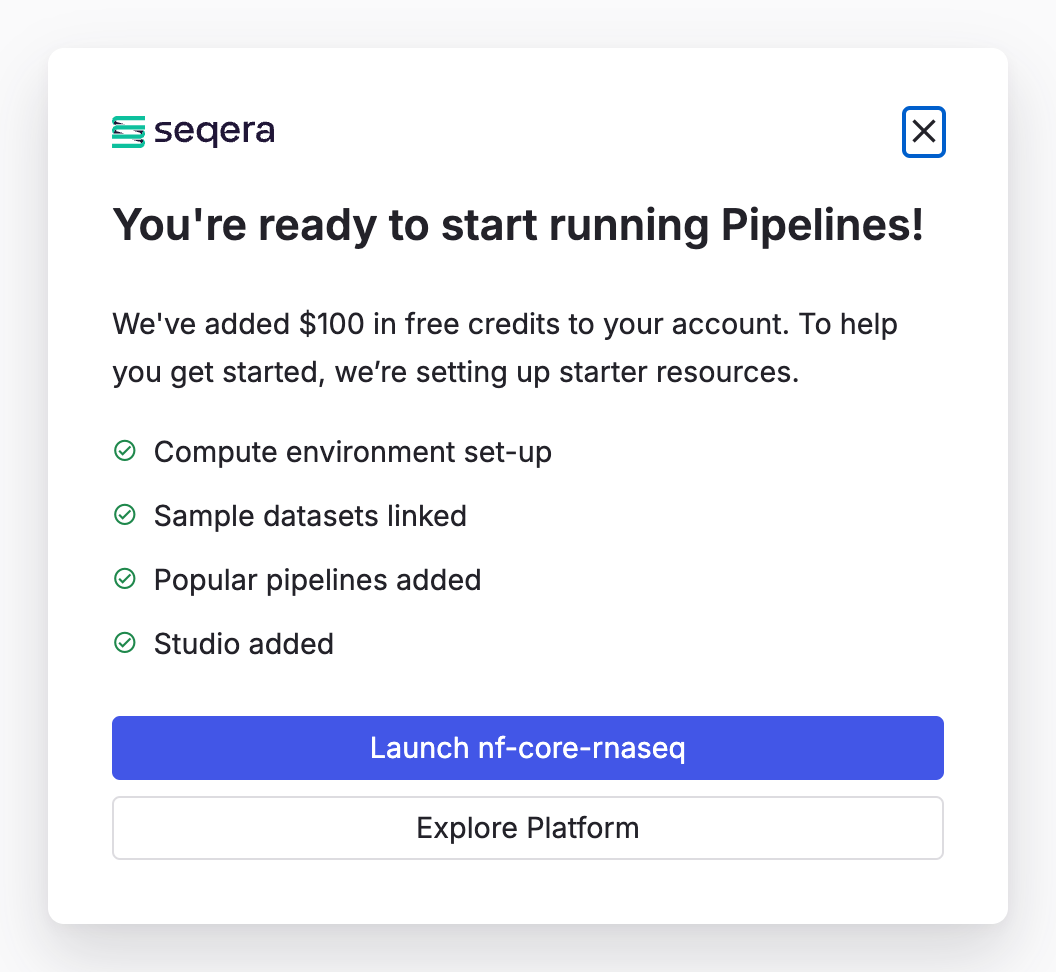
Your workspace includes:
- A Seqera Compute environment with $100 in free credits for pipelines and Studios
- The credentials your compute environment uses to manage cloud resources for you
- A cloud storage bucket for your pipeline data, and a bucket of example data, in Data Explorer
- Six preconfigured pipelines on the Launchpad. The nf-core pipelines run on test data.
- An input dataset for each nf-core pipeline
- A VS Code Studio
Launch nf-core/rnaseq
nf-core/rnaseq analyzes RNA sequencing data. It runs quality control, trims and aligns reads, and quantifies gene expression. The preconfigured pipeline uses the test profile and a small test dataset.
To launch the pipeline:
-
In the welcome dialog, select Launch nf-core-rnaseq. You can also select Launch nf-core-rnaseq in the banner at the top of the page.
The launch form opens on the Run parameters step. The
inputfield points to thenf-core-rnaseq-inputdataset, andoutdirhas a default value.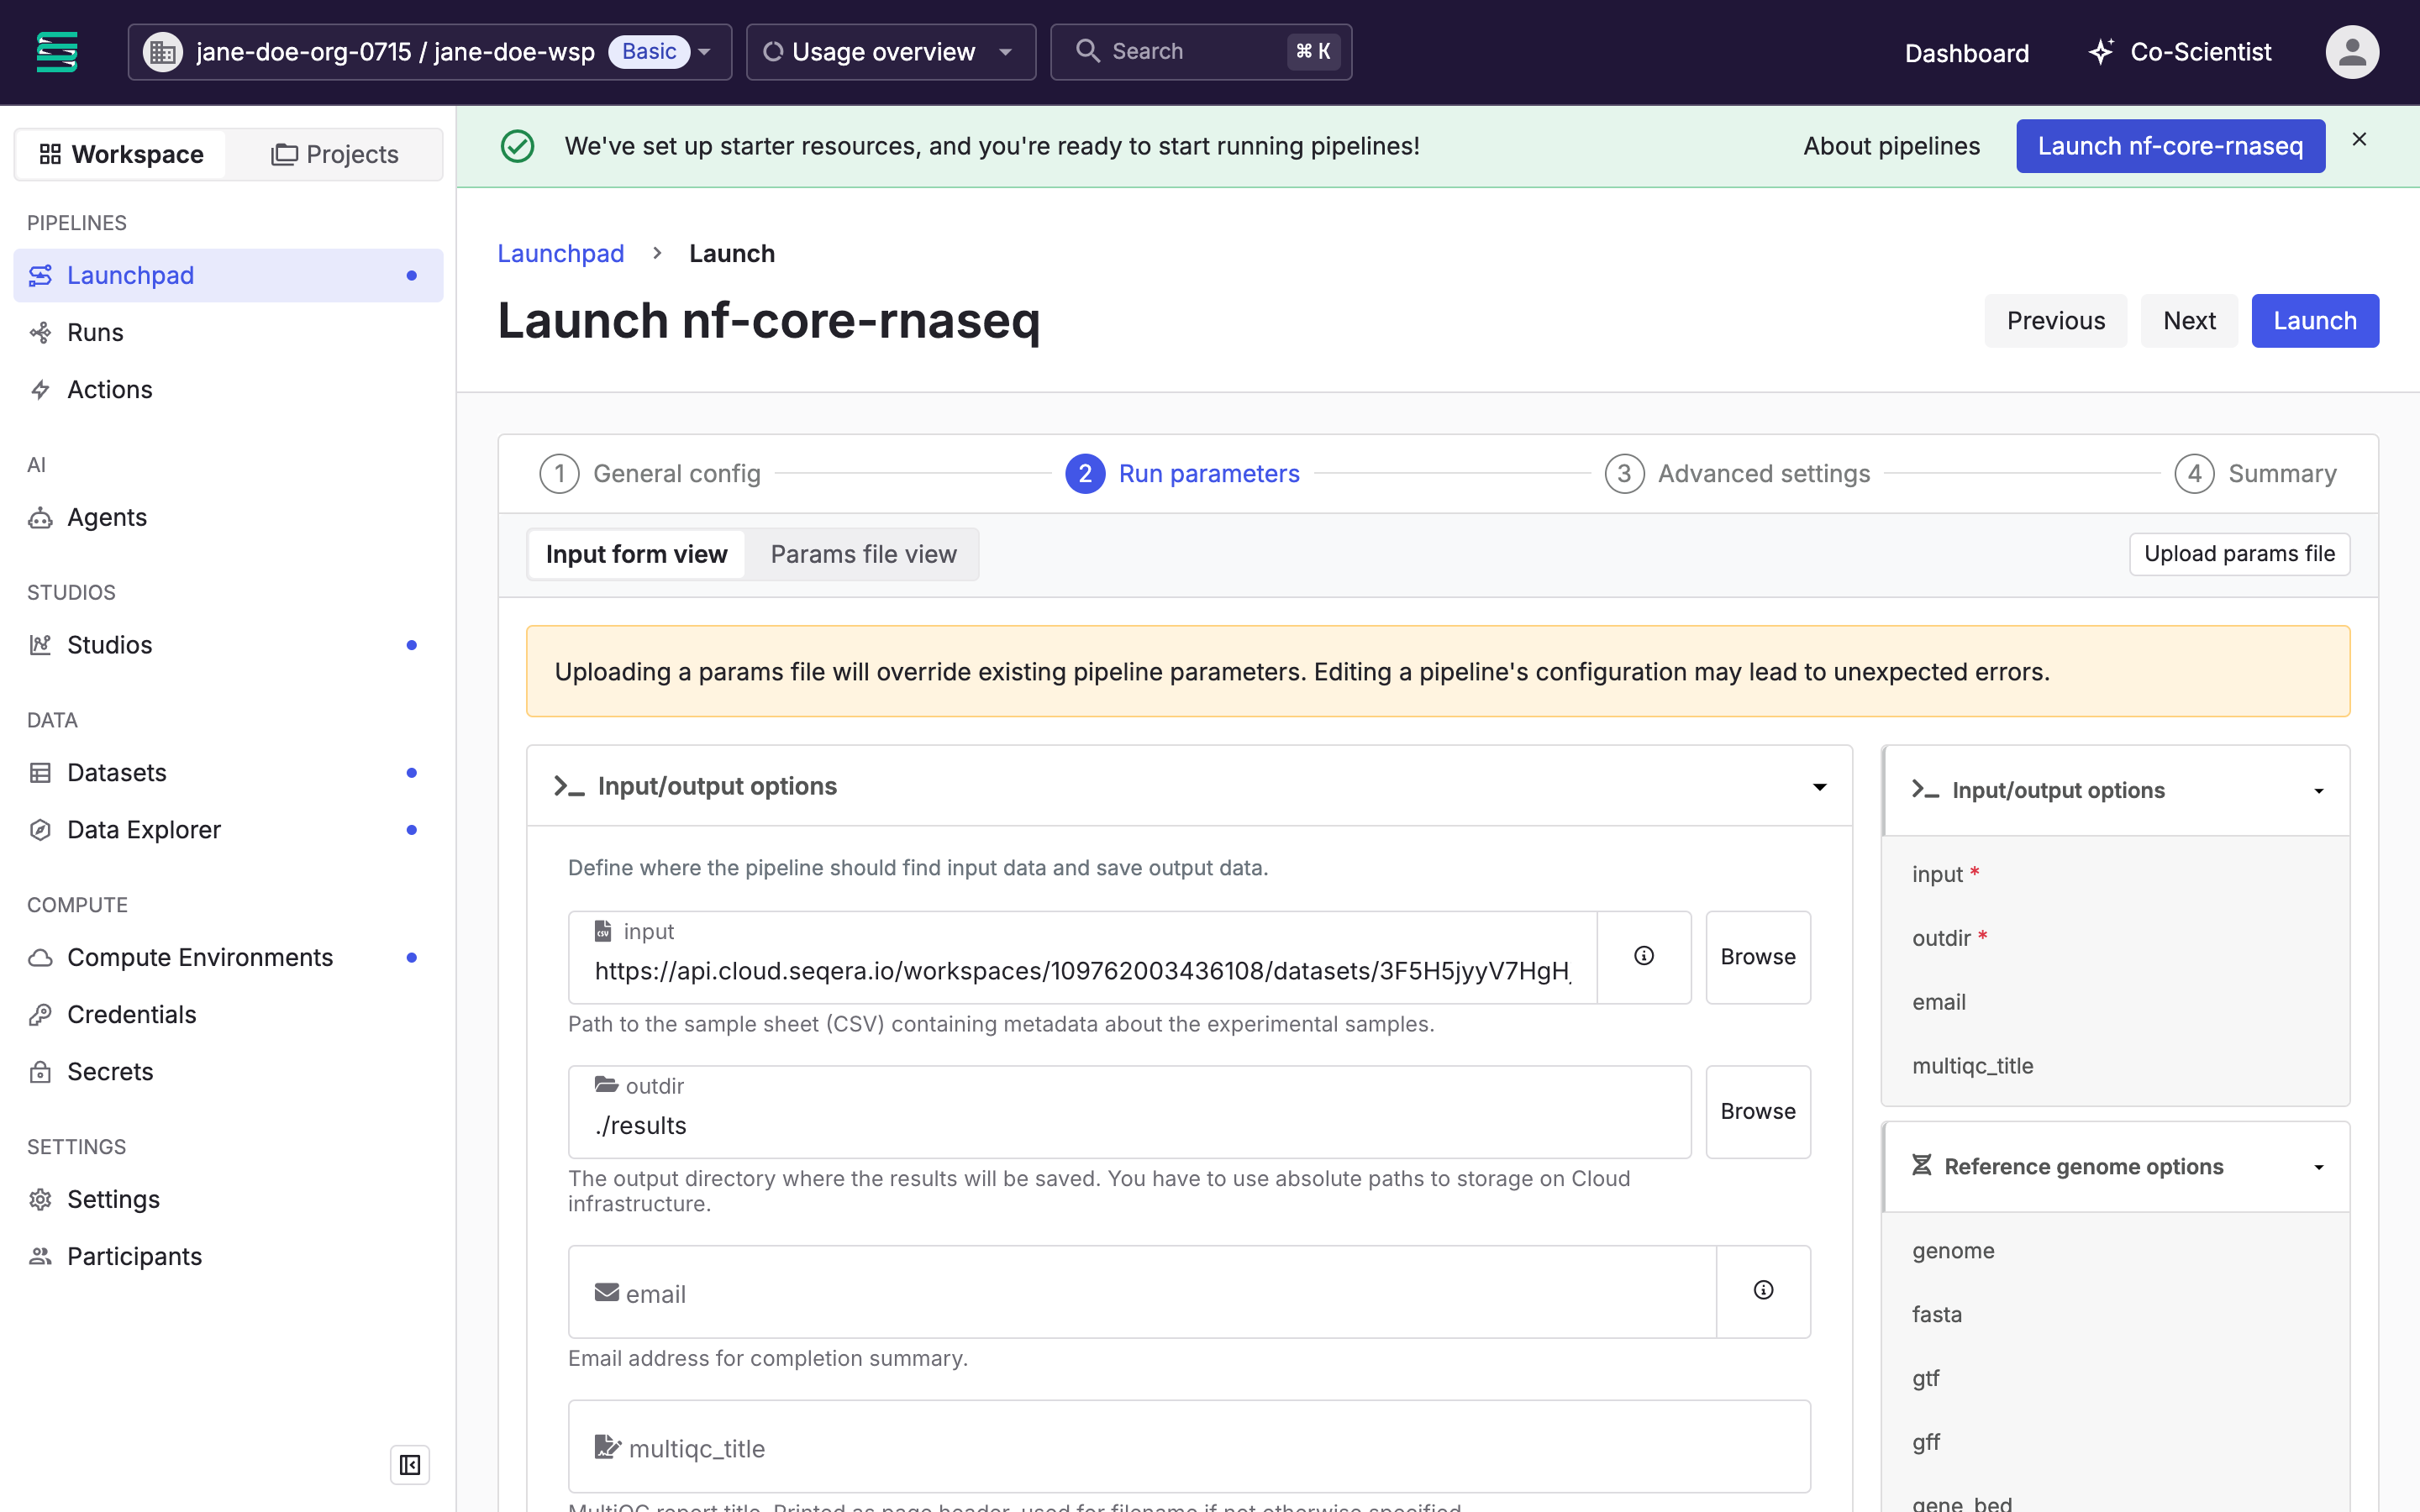
-
Optional: Select General config to change the Workflow run name or add Labels.
-
Select Launch.
Platform opens the Runs list. Your run appears with a Submitted status.
To launch any pipeline in your workspace, select Launch next to it on the Launchpad.
Monitor the run
The run details page shows the progress of your run. The test run takes about 15 minutes.
To open the run details page, select your run in the Runs list.
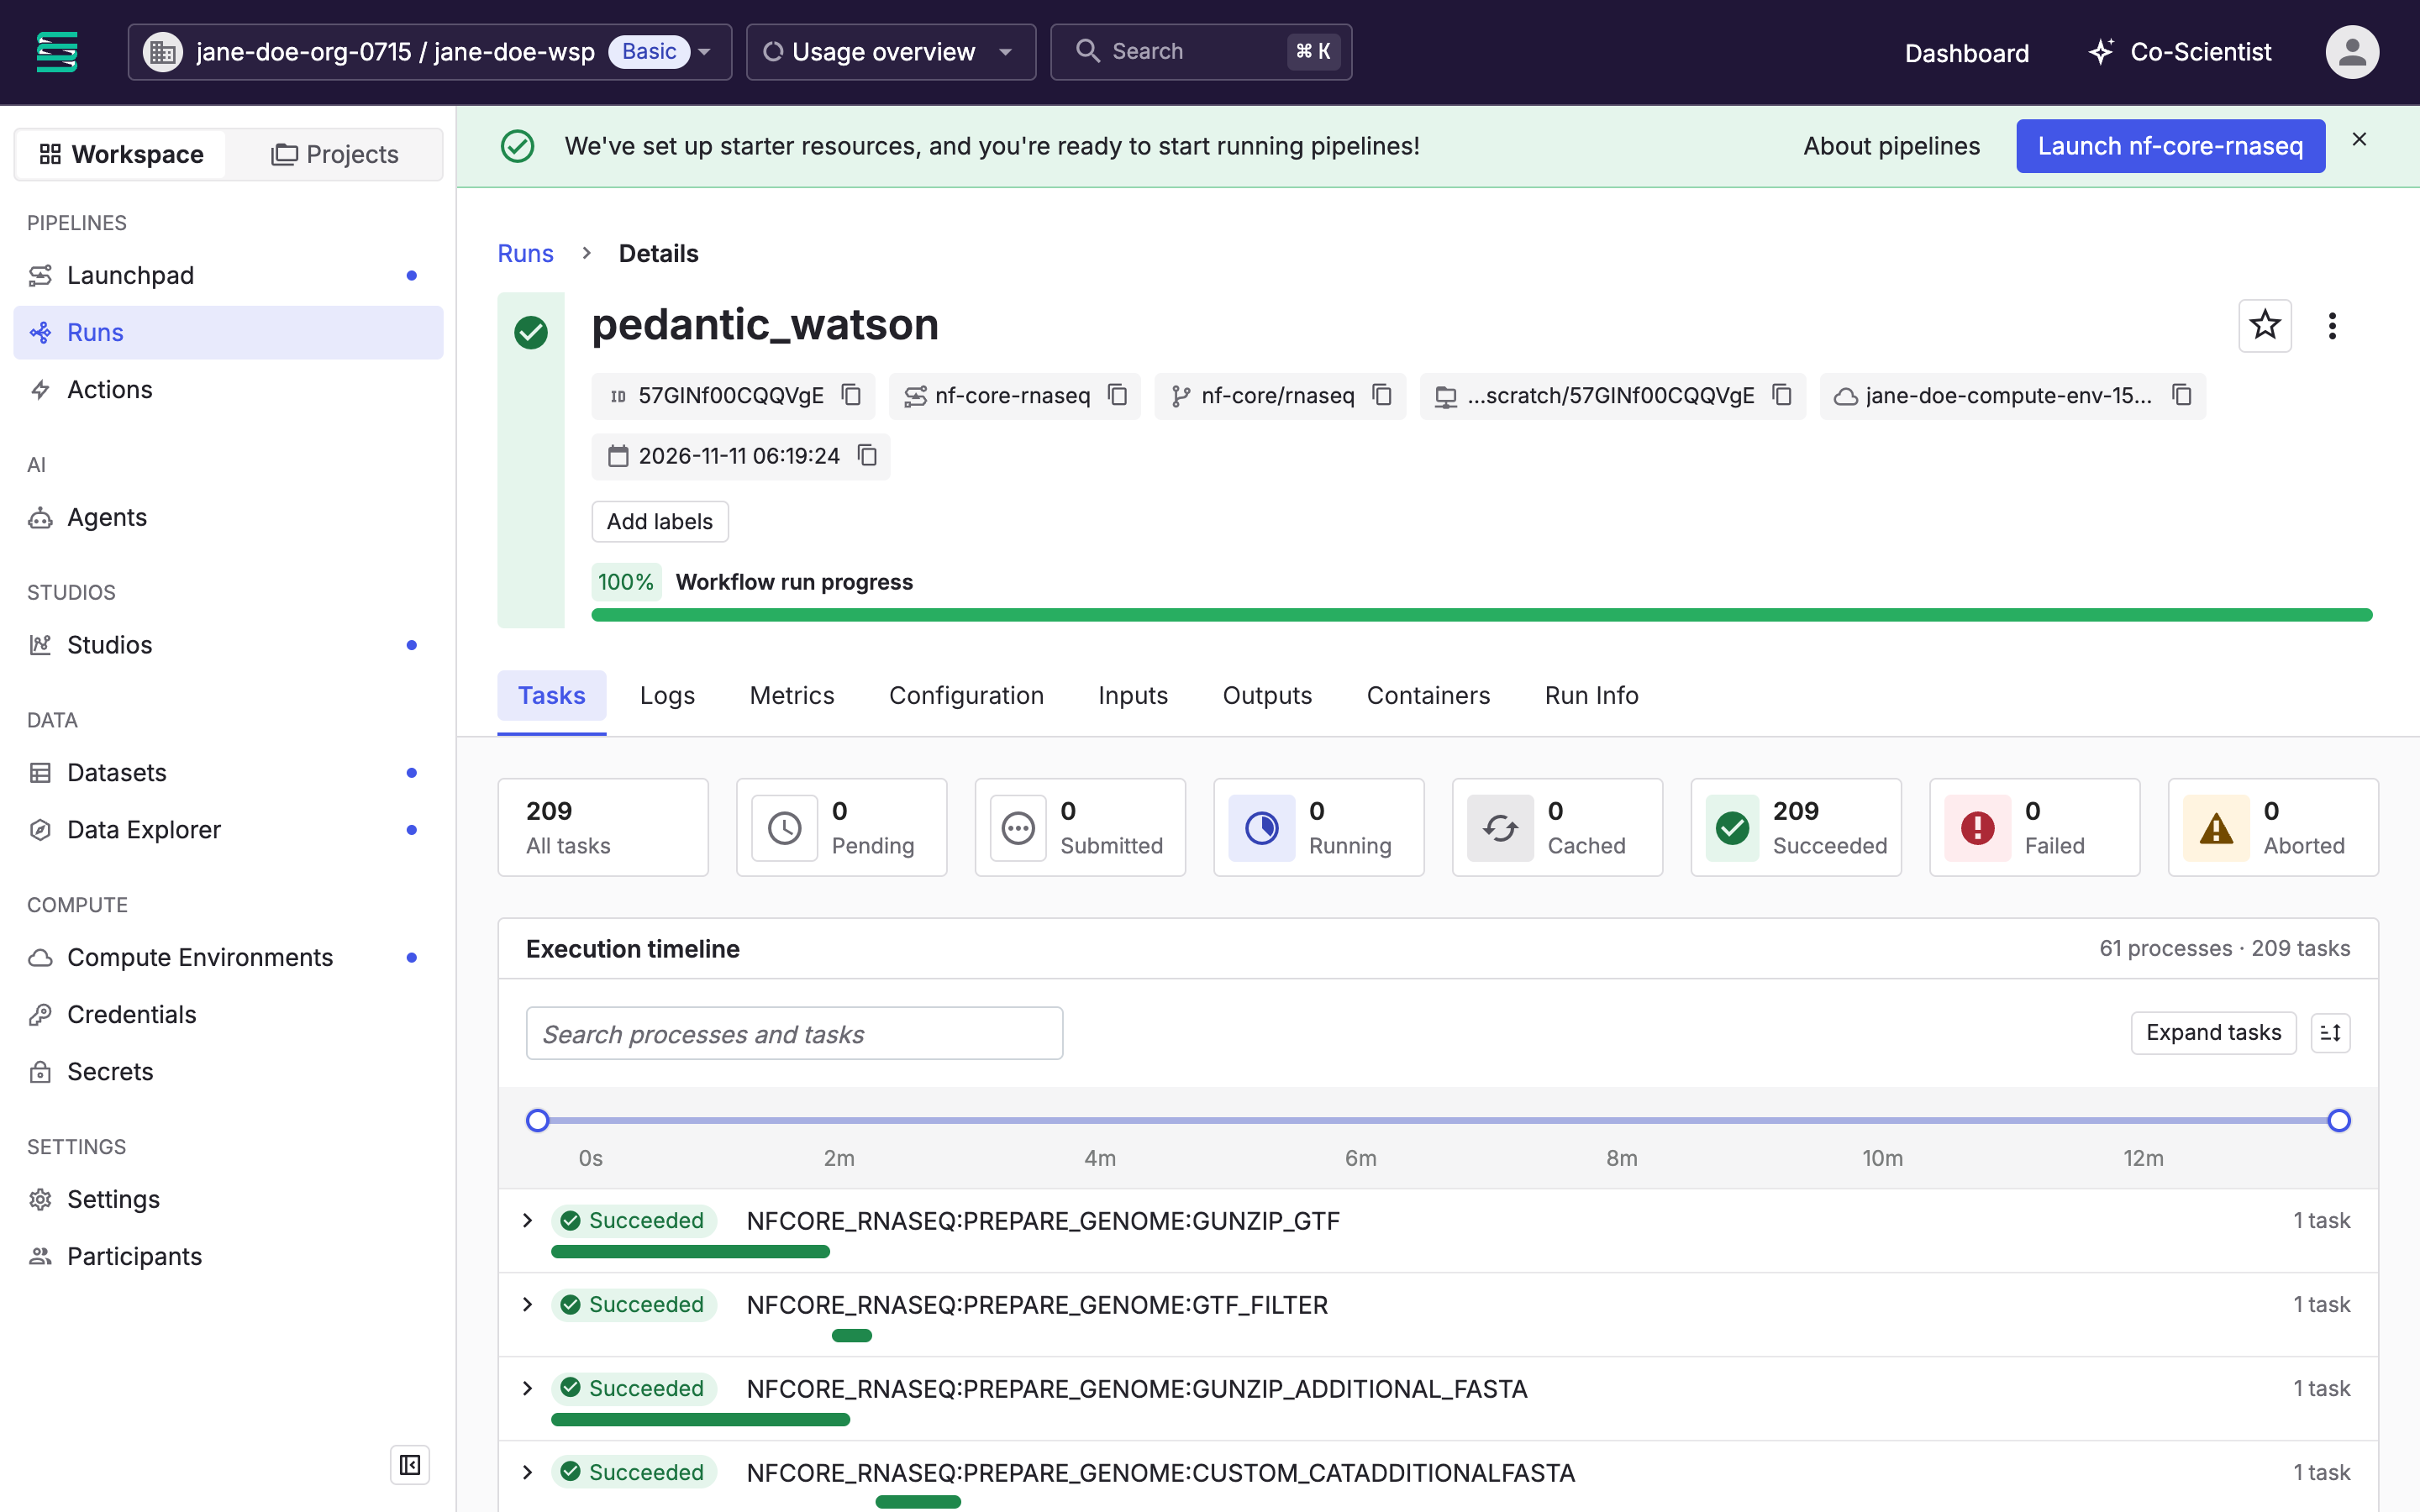
The header shows the run name and status, and a progress bar tracks the run. The Tasks tab counts tasks by status and plots each process on an execution timeline. The other tabs show the run's logs, metrics, configuration, inputs, outputs, containers, and run information.
When the run succeeds, select the Outputs tab. The Reports section lists the reports the pipeline generated. Select MultiQC HTML report to preview the quality control summary for all samples.
See Run details for a description of each tab, or Explore the Community Showcase for a guided tour.
View the input dataset
Datasets store samplesheets that you can select as pipeline input. The run used the nf-core-rnaseq-input dataset as its input.
To view the dataset, select Datasets in the left navigation menu. The Runs column shows how many runs used each dataset.
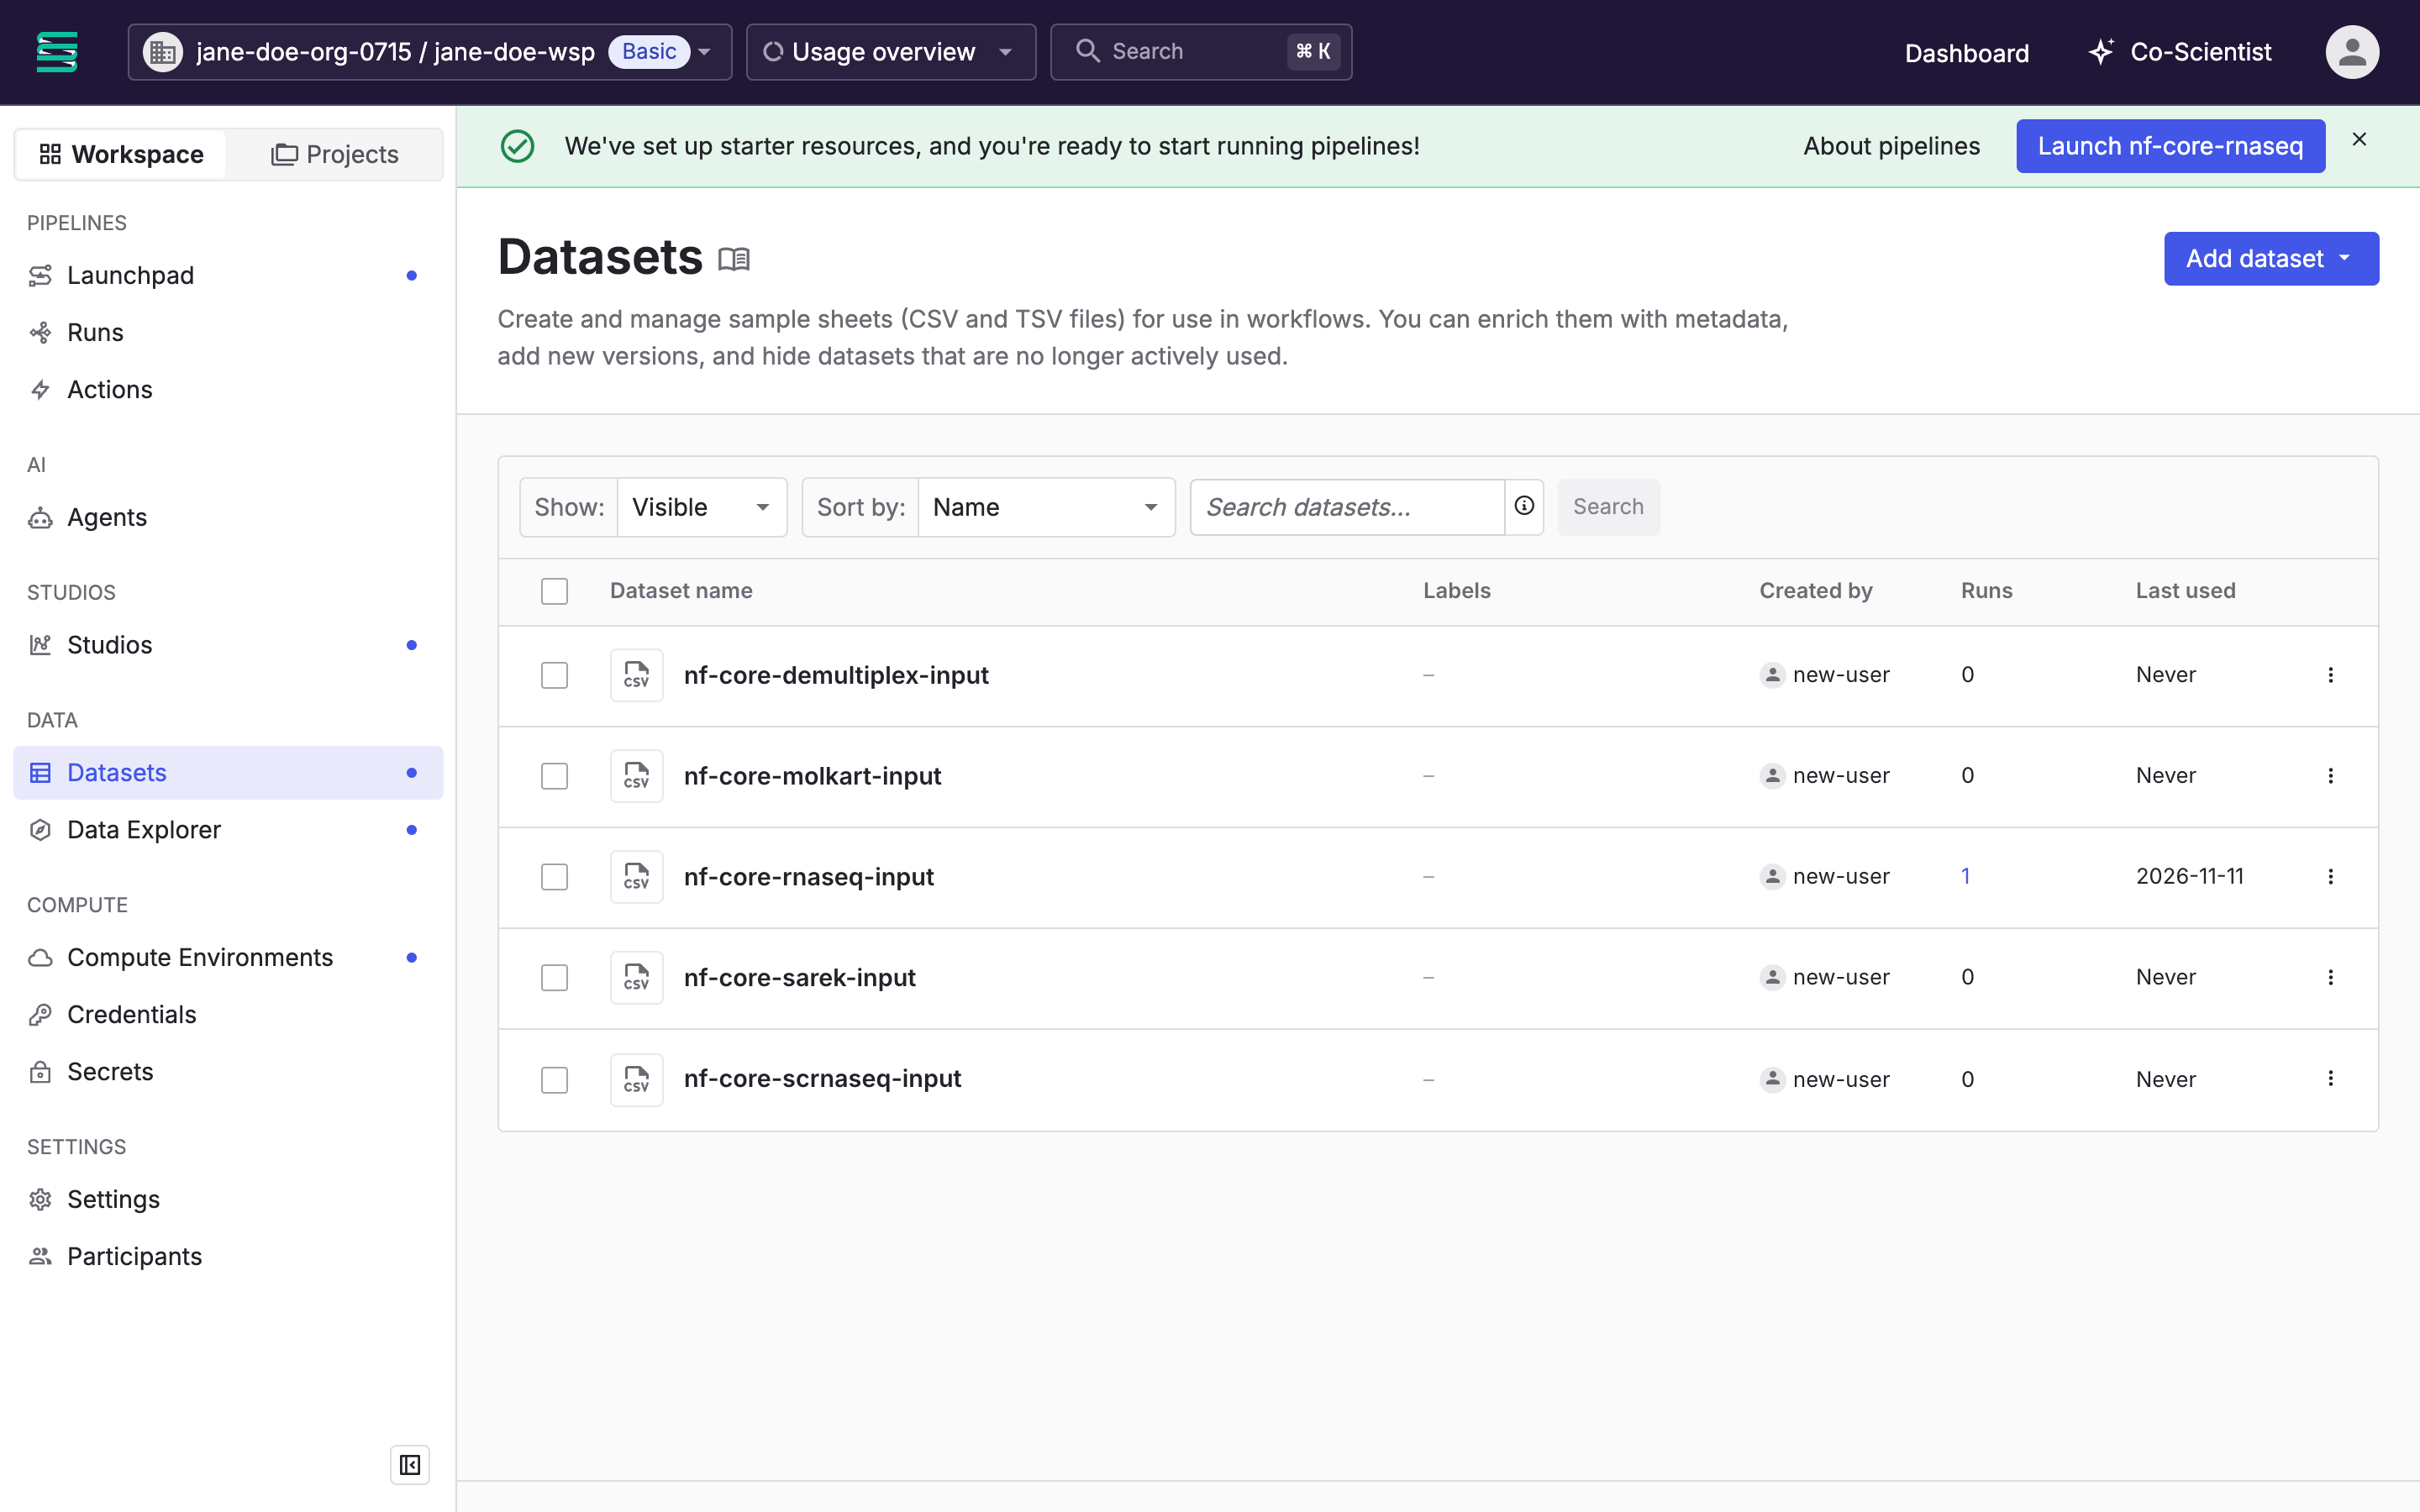
Select nf-core-rnaseq-input to view its samplesheet.
Browse the results in Data Explorer
Use Data Explorer to browse cloud storage in Platform. The run published its results to your workspace bucket.
To browse the results:
- Select Data Explorer in the left navigation menu.
- Select your workspace bucket. It has the same name as your compute environment, plus a suffix.
- Open
nf-core-rnaseq/<run-id>/results/.
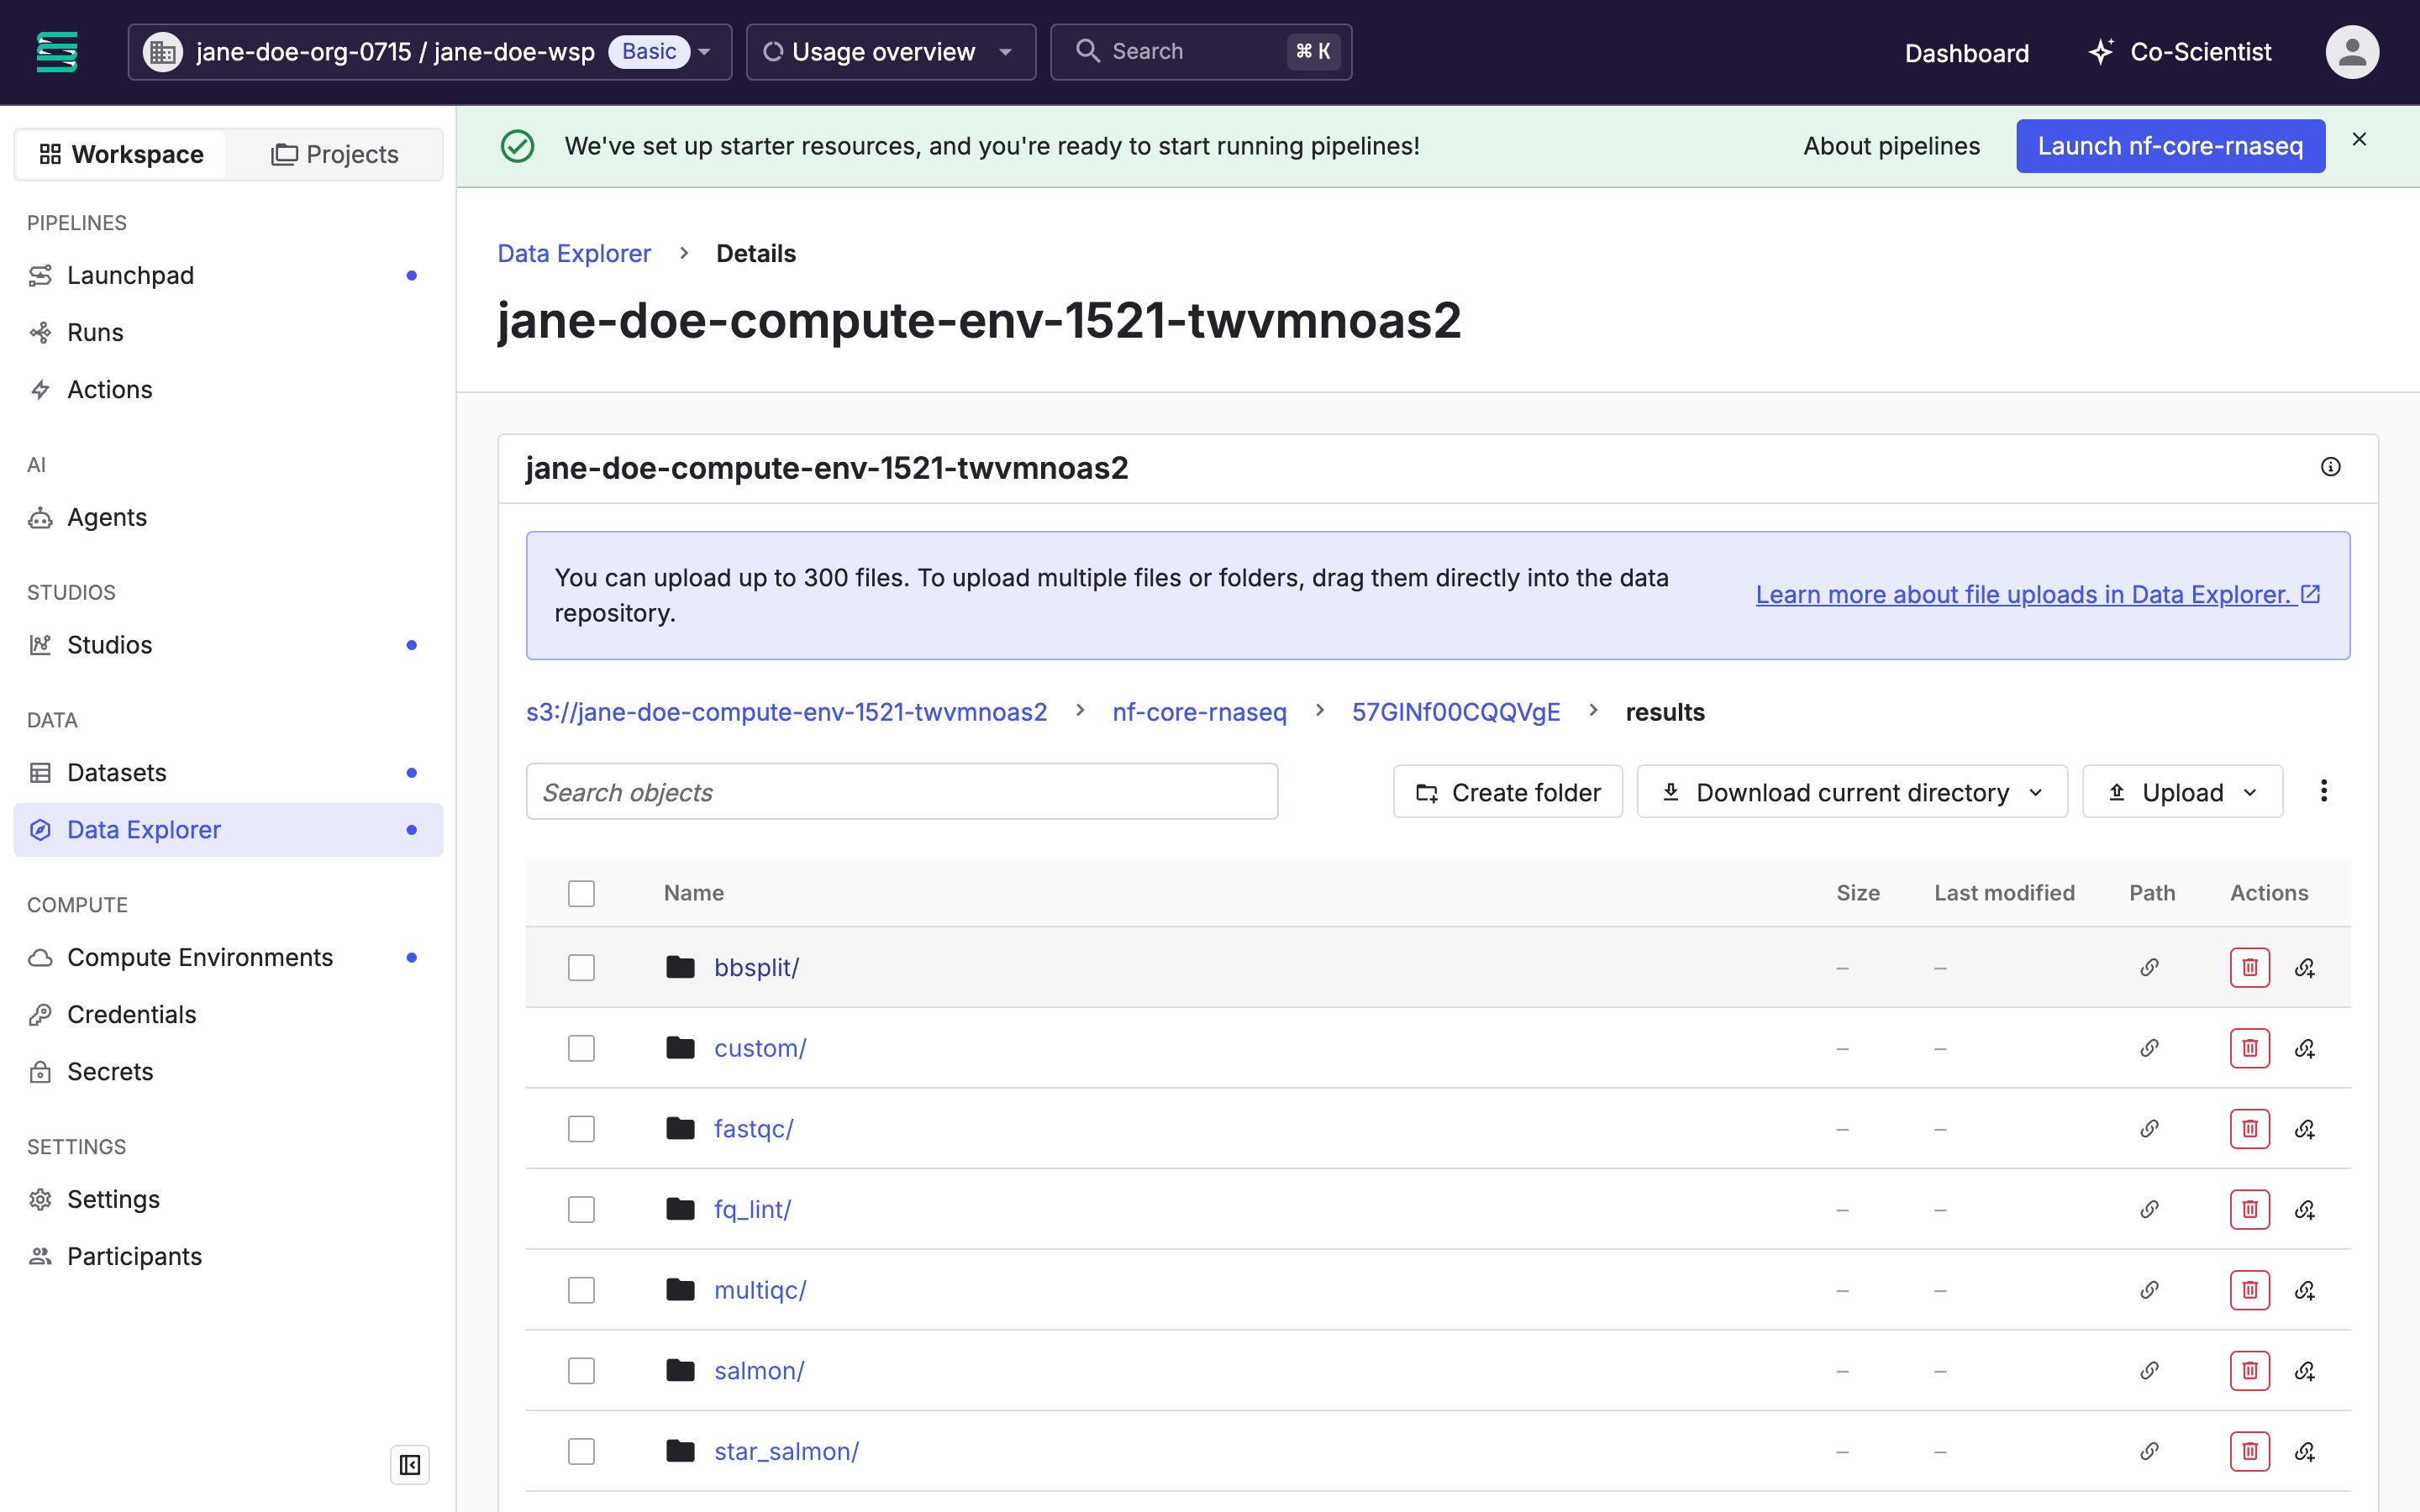
The results directory has a subdirectory for each analysis step, such as fastqc, multiqc, and salmon. Select a file to preview it, or download it.
Your workspace also includes the example-datasets bucket, which holds sample data you can use as pipeline input.
Analyze results in a Studio
Studios are interactive environments, such as VS Code or JupyterLab, that run on your compute environment. Your workspace includes a stopped VS Code Studio. Mount your workspace bucket to work with the run's results.
To start the Studio:
-
Select Studios in the left navigation menu.
-
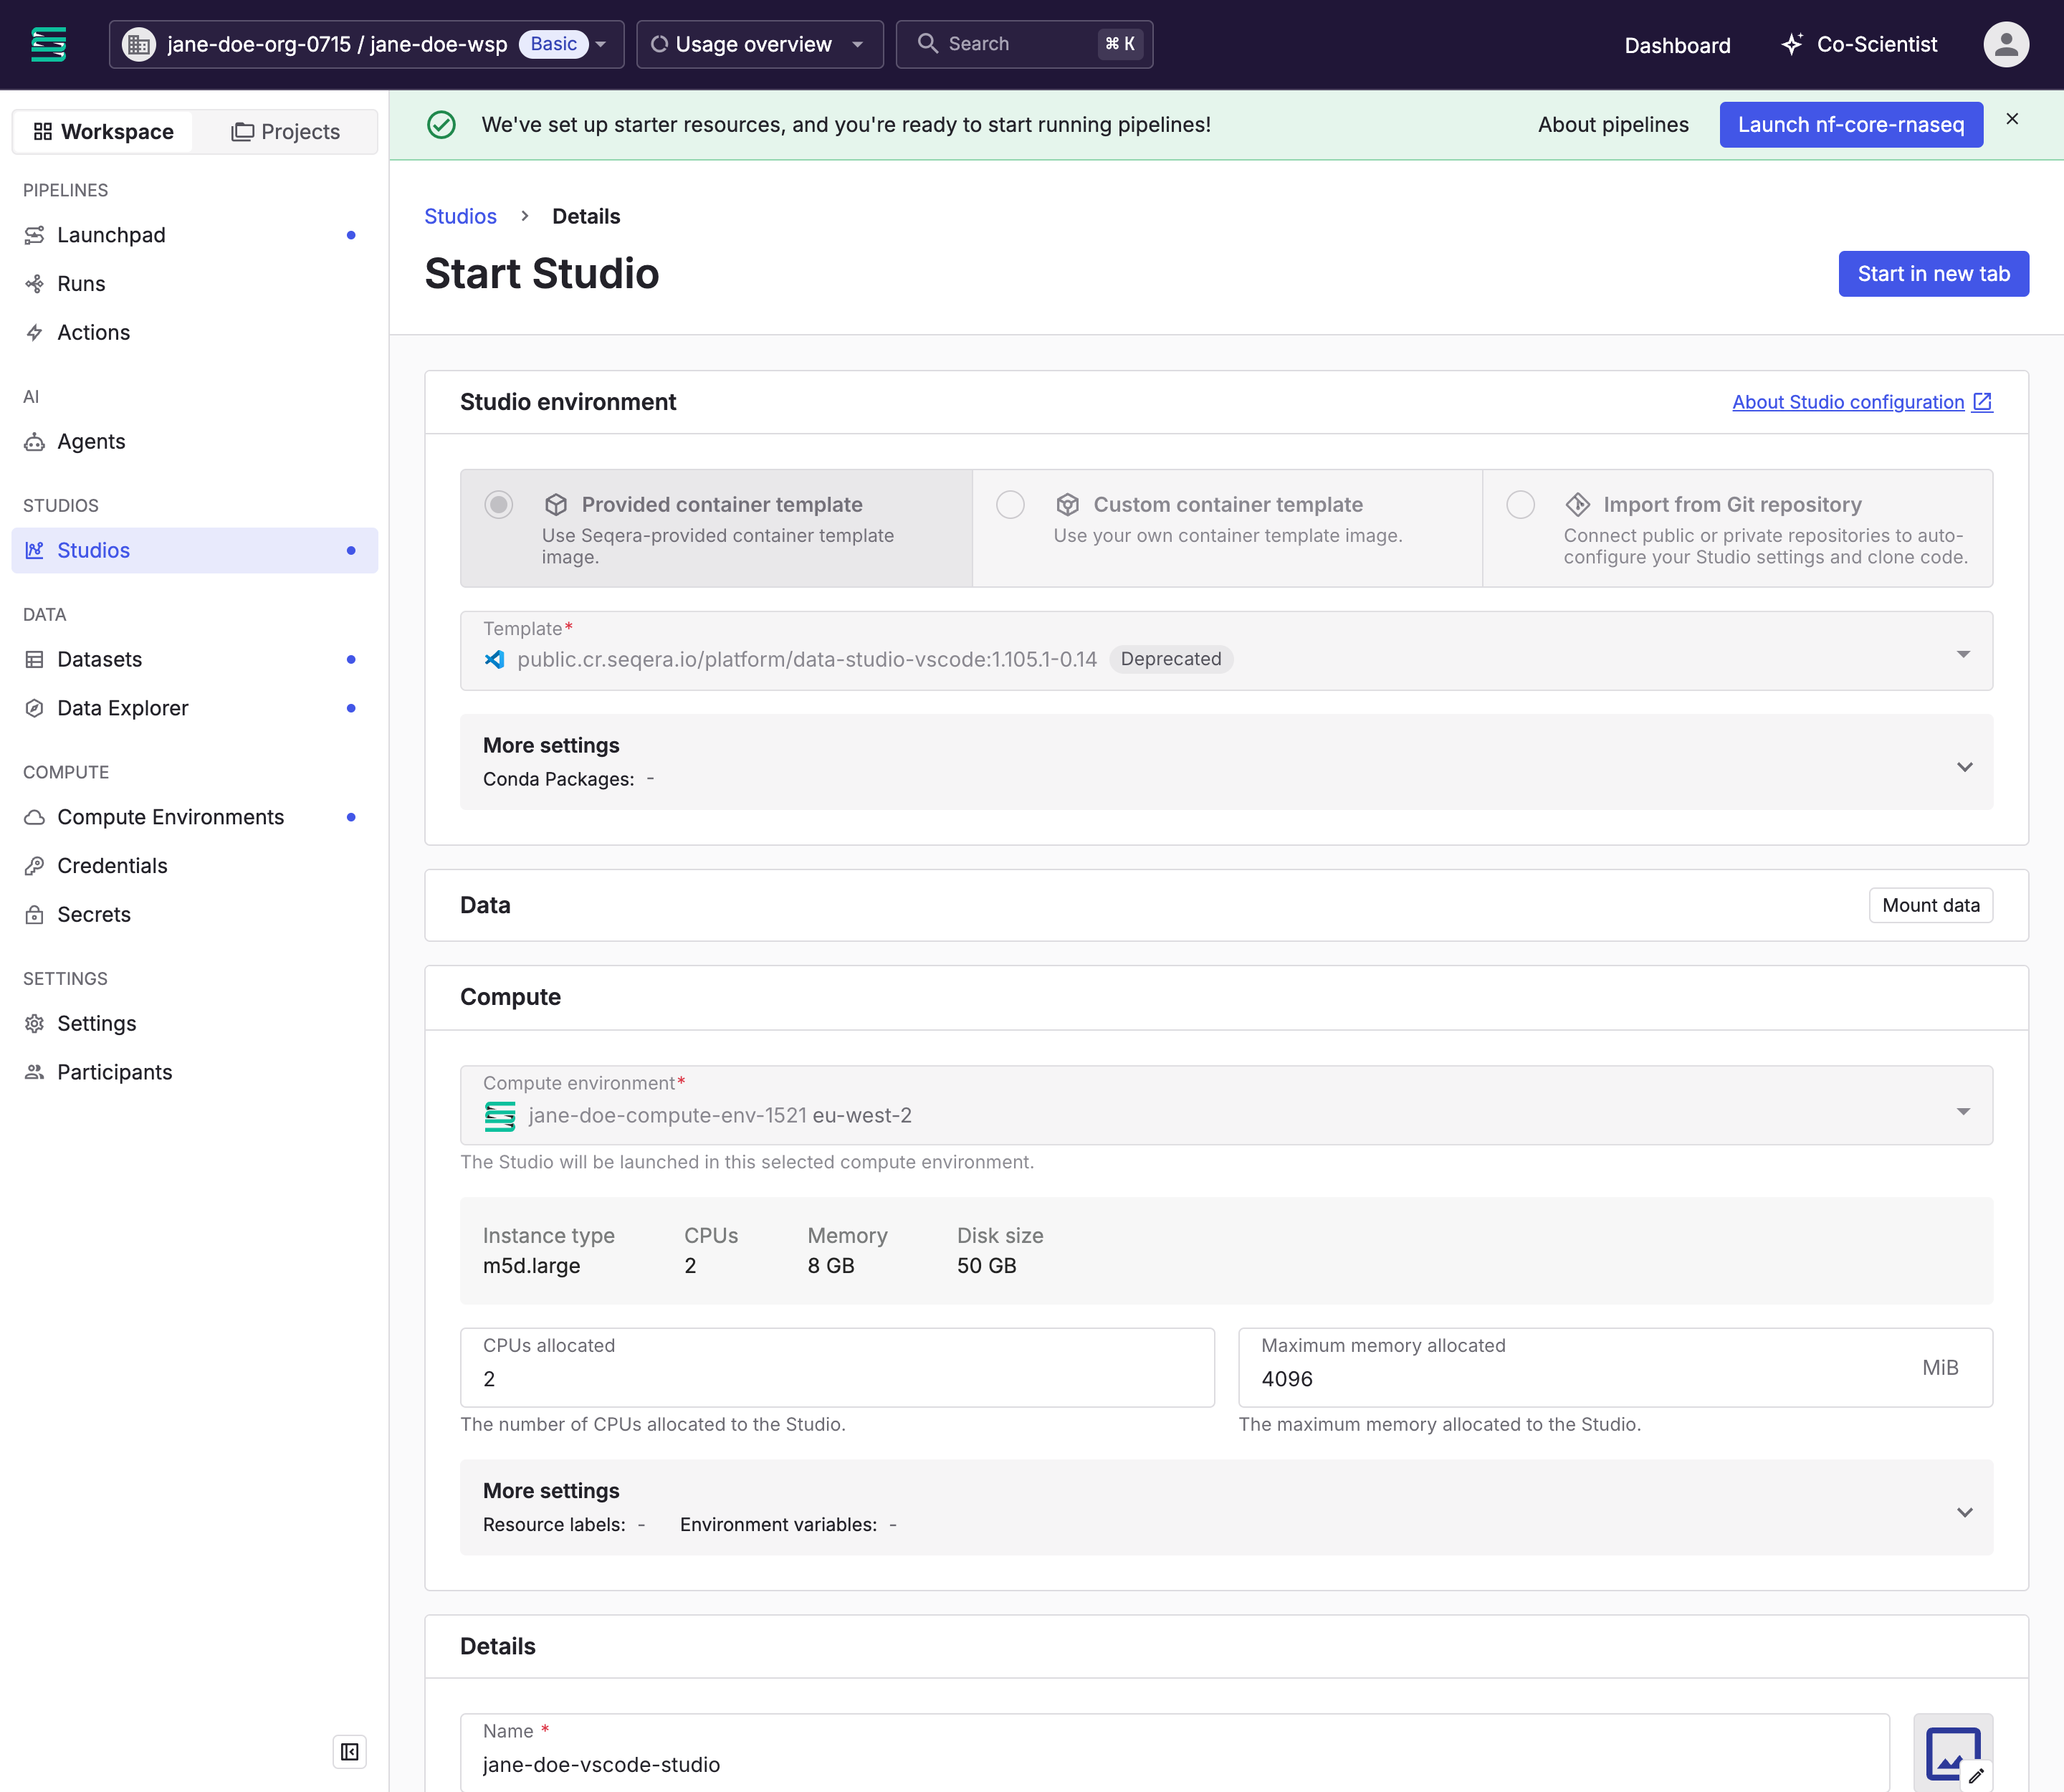
Select Start next to the VS Code Studio.
-
Under Data, select Mount data.
-
Select Add to mount list next to your workspace bucket, then select Mount data.
-
Optional: Change the CPUs allocated or Maximum memory allocated.
-
Select Start in new tab.
The Studio opens in a new browser tab when it's ready. Your bucket is at /workspace/data/<bucket-name>. The run's results are in /workspace/data/<bucket-name>/nf-core-rnaseq/<run-id>/results/.
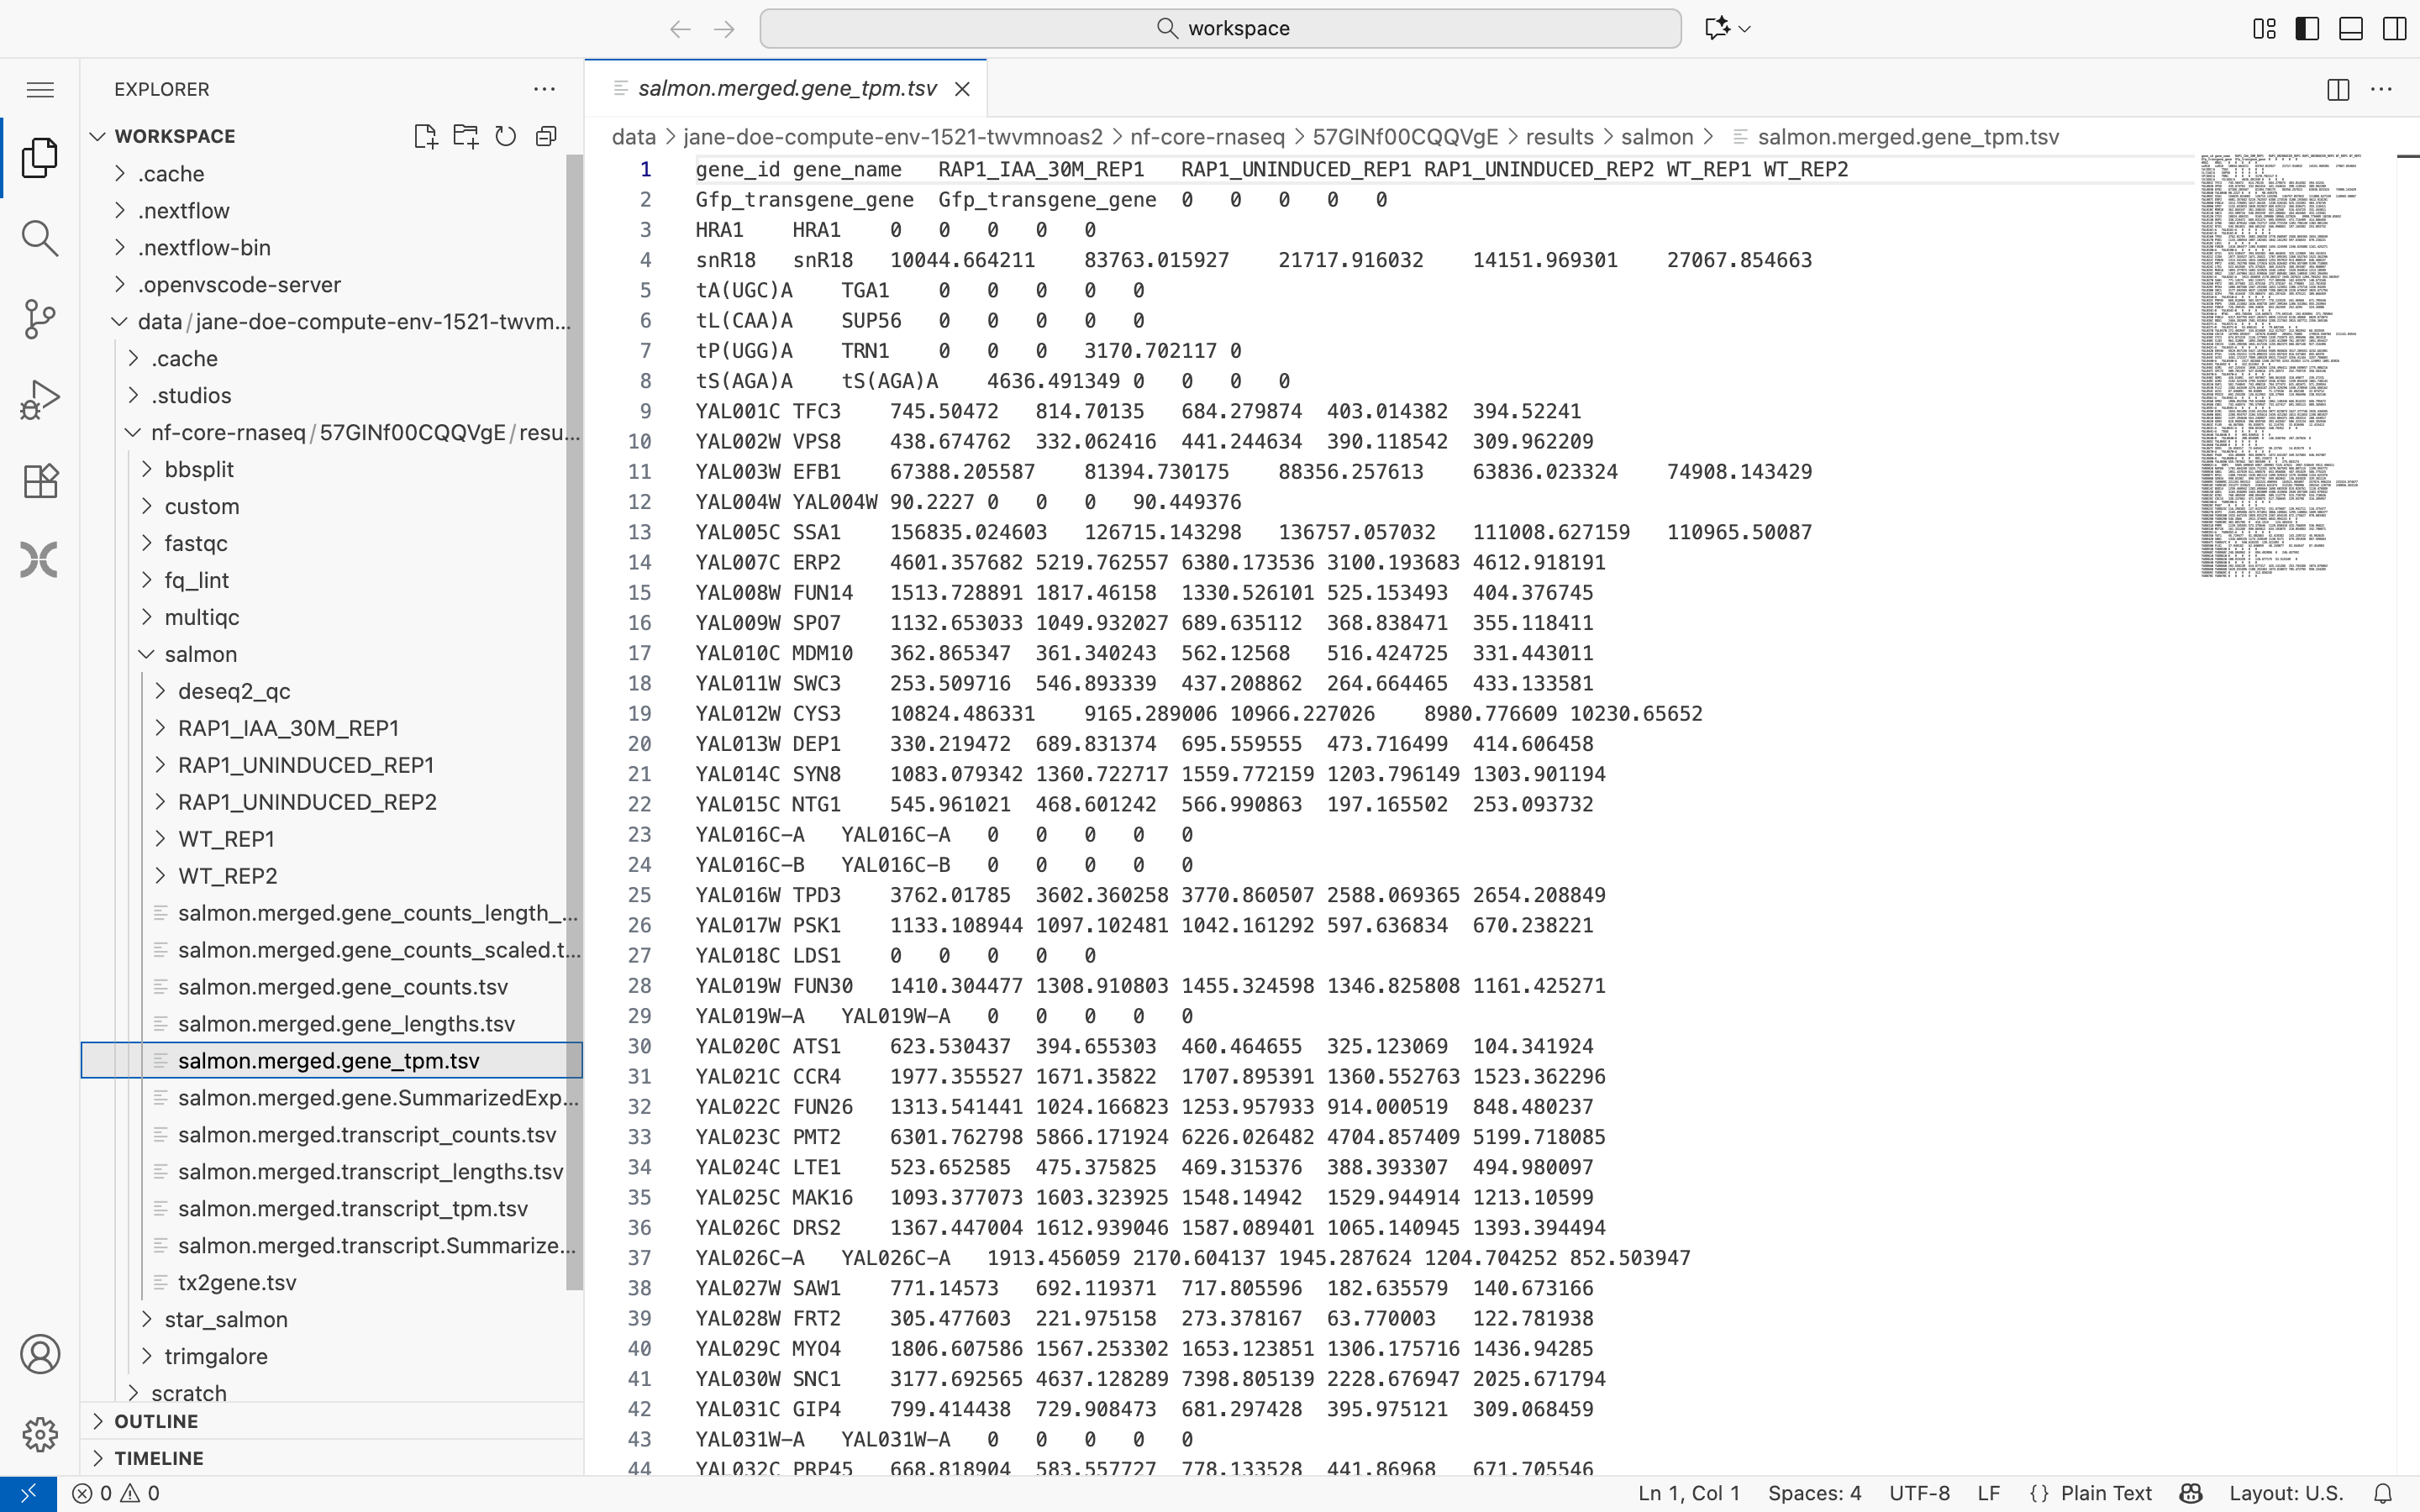
A running Studio uses credits until it stops. When you finish, select Studios, open the Studio actions menu next to the Studio, and select Stop. Otherwise, the Studio stops automatically after 8 hours.
Your organization can run one Studio at a time on the free tier.
See Studios to create more Studios.
View the compute environment
Your Seqera Compute environment runs your pipelines and Studios. You don't need a cloud account or any configuration.
To view it, select Compute Environments in the left navigation menu.
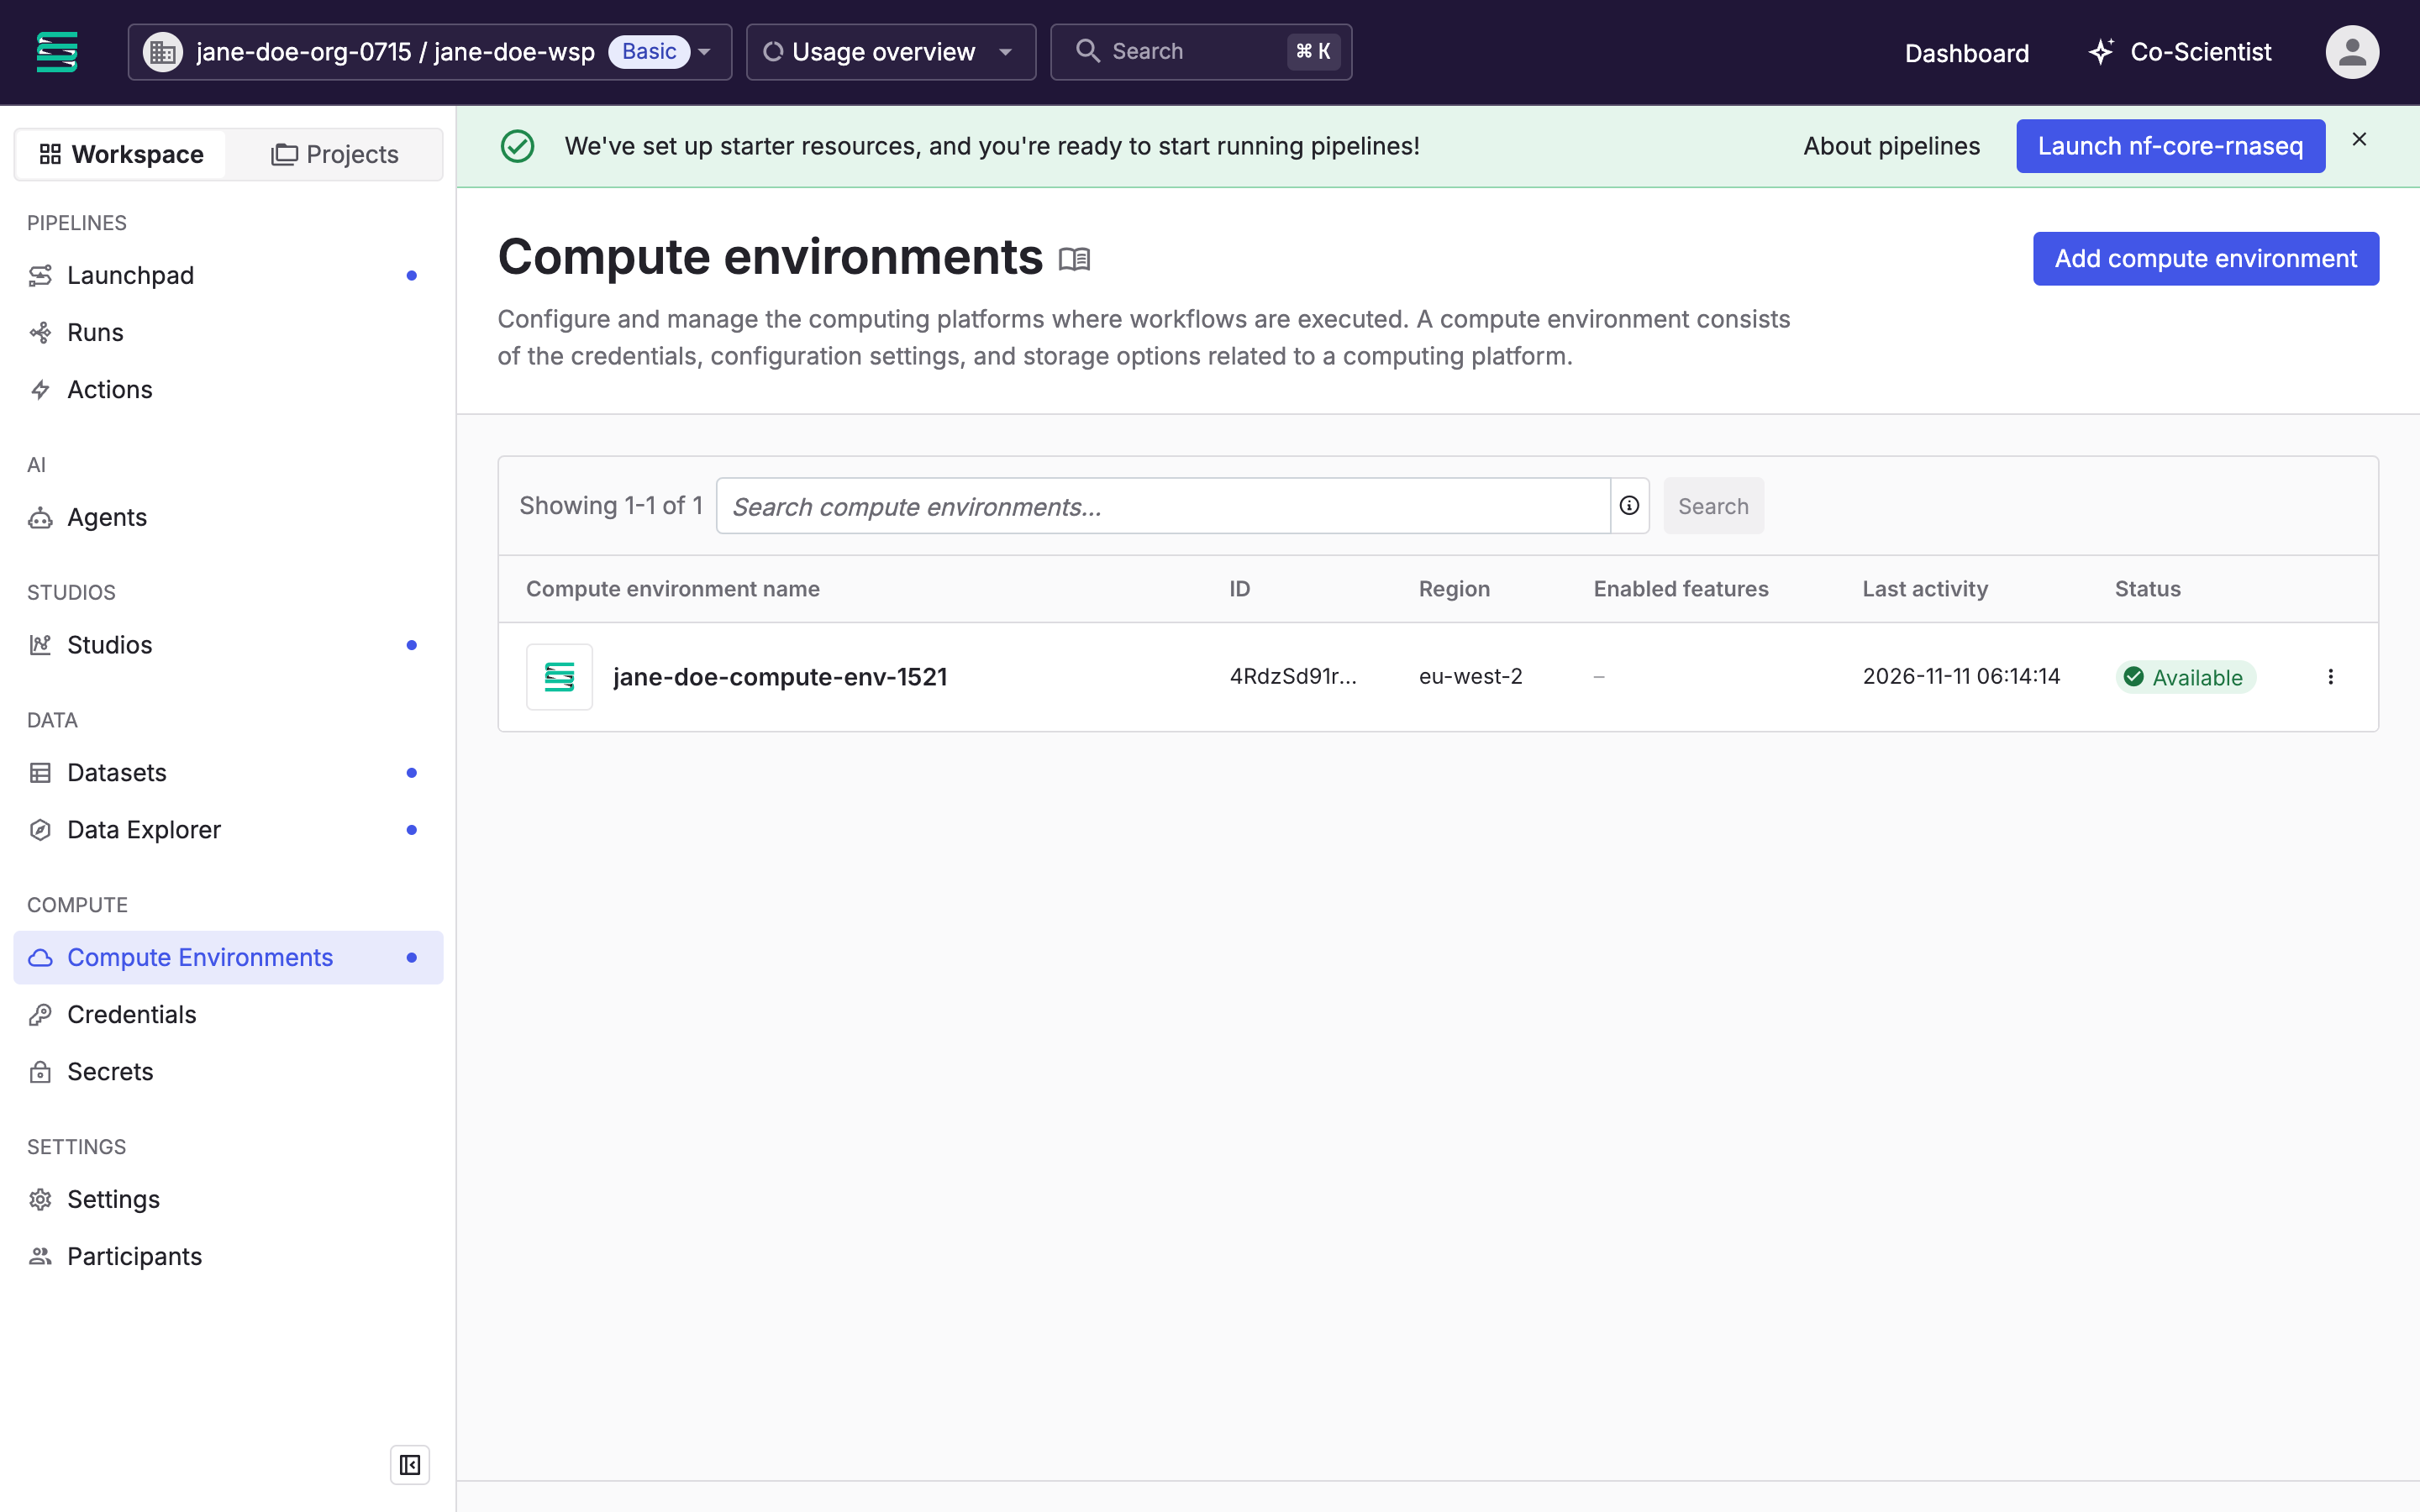
Your run's tasks consume credits based on the CPU, memory, network, and storage they use.
To check your balance, select Usage overview in the top navigation bar. It shows your credits, CPU hours, and your organization's limits, such as concurrent runs, running Studio sessions, and users. See Credit management to monitor usage and request more credits.
Delete work directory files and other data you no longer need to free up storage.
Next steps
Your Launchpad has five more pipelines to try:
- nextflow-io/hello: A minimal pipeline to check that your compute environment works
- nf-core/demultiplex: Separates pooled sequencing reads into samples by barcode
- nf-core/molkart: Processes Molecular Cartography spatial transcriptomics data
- nf-core/sarek: Detects and annotates germline and somatic variants
- nf-core/scrnaseq: Processes single-cell RNA sequencing data
When you're ready to use your own data and pipelines:
- Add data
- Add pipelines
- Add participants to collaborate with your team
For help, ask in the Seqera community forum or ask Co-Scientist.